Groq 3 LPX Rack-Scale Inference System: Redefining Inference Infrastructure
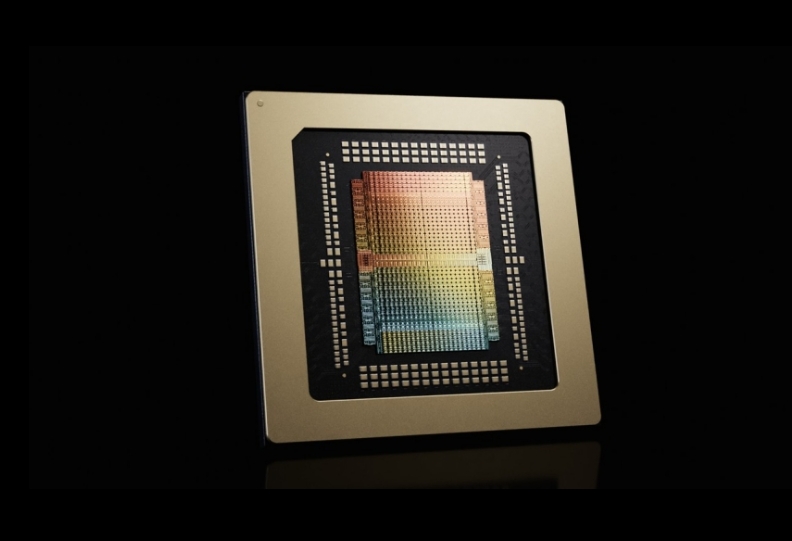
The Groq 3 LPX, a rack-mounted LPU (Language Processing Unit) inference hardware system launched after acquiring the Groq team, deviates from the general-purpose GPU route.
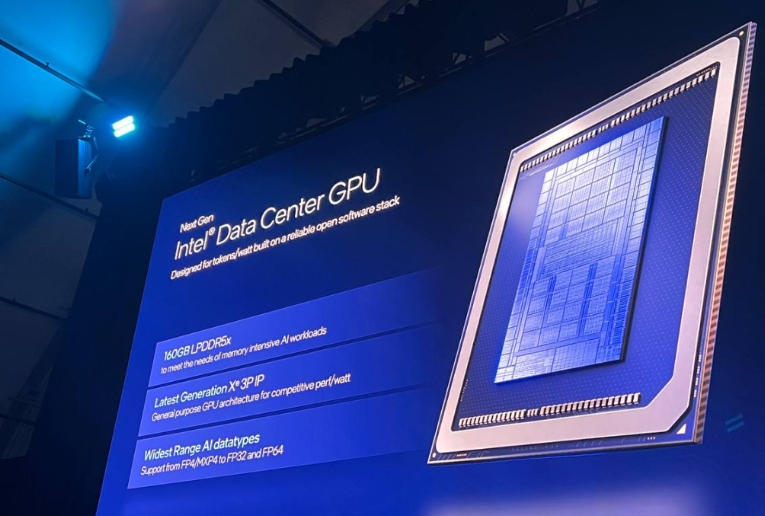
An application-specific integrated circuit engineered solely to run trained-model inference (rather than general training), optimized for low power, fixed workloads and cost efficiency. Custom inference ASICs let hyperscalers reduce reliance on GPUs and lower tokens-per-watt costs at cloud scale.
The Groq 3 LPX, a rack-mounted LPU (Language Processing Unit) inference hardware system launched after acquiring the Groq team, deviates from the general-purpose GPU route.
It focuses on massive memory capacity, air-cooled deployment, and low-cost inference, rather than the large-model training market.
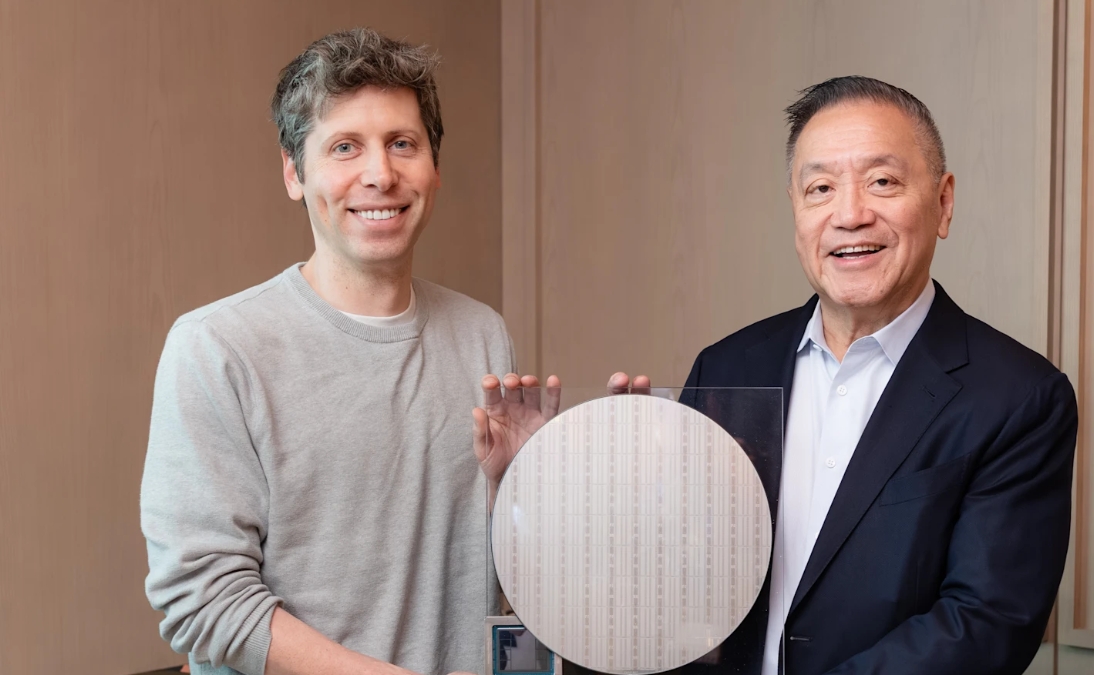
OpenAI, in collaboration with Broadcom, unveiled “Jalapeño,” a proprietary ASIC dedicated to inference.